Course Overview
5 min readFrom producers and consumers to rebalancing storms and exactly-once semantics — built on real failure scenarios, not toy examples. The architectural instinct that separates engineers who use Kafka from those trusted to design it.

Introduction
Every large-scale system you admire — Netflix's recommendation engine, Uber's live tracking, LinkedIn's activity feeds — has one thing in common under the hood: a stream of events flowing in real time, reliably, at massive scale. That backbone is almost always Apache Kafka.
This course takes you from "what even is a topic?" to confidently designing, building, and operating Kafka-based systems in production. No hand-waving, no toy examples that fall apart the moment you add a second consumer. You'll work with real producers and consumers, real partitioning decisions, and the same failure scenarios that show up in on-call incidents — broker outages, consumer lag spikes, rebalancing storms — so what you learn here transfers directly to your job.
Mastering Kafka's core concepts helps you build real-time systems and design event-driven applications confidently.
What You Will Learn
The course covers why Kafka exists Kafka's, what real-world problem it solves that other messaging tools doesn't, its core architecture, producer and consumer internals, consumer groups, schema management, stream processing, and cluster operations. You will learn through theoretical lessons and hands-on coding exercises, ensuring practical experience.
Key concepts like partitioning strategy, delivery guarantees, and rebalancing behavior will be explored in depth.
Upon completing this course, you can design, build, and operate Kafka-based systems in production with confidence.
- Everything you need to know about Kafka's core architecture.
- Why brokers, topics, and partitions are structured the way they are.
- How the log-based design enables both durability and speed.
- Why Kafka’s log-based design enables both durability and speed — and when that model works against you
- How brokers, topics, and partitions are structured, and the invariants that hold them together
- Producer internals: acknowledgment levels, batching, idempotence, and what
acks=allactually guarantees (and doesn’t) - Consumer internals: offset management, commit strategies, and why
auto.commitsilently loses messages - Consumer groups, partition assignment, and how to stop rebalancing storms before they cascade
- Schema management with Avro and Protobuf, Schema Registry compatibility modes, and what breaks when you evolve a schema wrong
- Log compaction, the status topic pattern, and exactly-once semantics end to end
- Kafka Streams for real-time processing without a separate cluster
- Kafka Connect for wiring Kafka into databases and data lakes without custom glue code
- Cluster internals: KRaft mode, ISR mechanics, leader election, and what happens during a broker loss
- Security: TLS, SASL, ACLs, and encryption at rest
- Observability: consumer lag, JMX metrics, distributed tracing across services
- Testing event-driven systems with Testcontainers and embedded Kafka
- Production operations: performance tuning, monitoring, and keeping a cluster healthy under load
- GitHub repository access: Kafka Mastery - GitHub repository — link coming soon.
By the numbers: 195 lessons · 13 chapters · 100+ diagrams · 1 companion GitHub repository · 0 toy examples
What You’re Going to Build
Every lesson in this course connects to one real system — a national passport lifecycle service that processes identity events at scale. By the time you’re done, here’s what you’ll have running on your own machine:
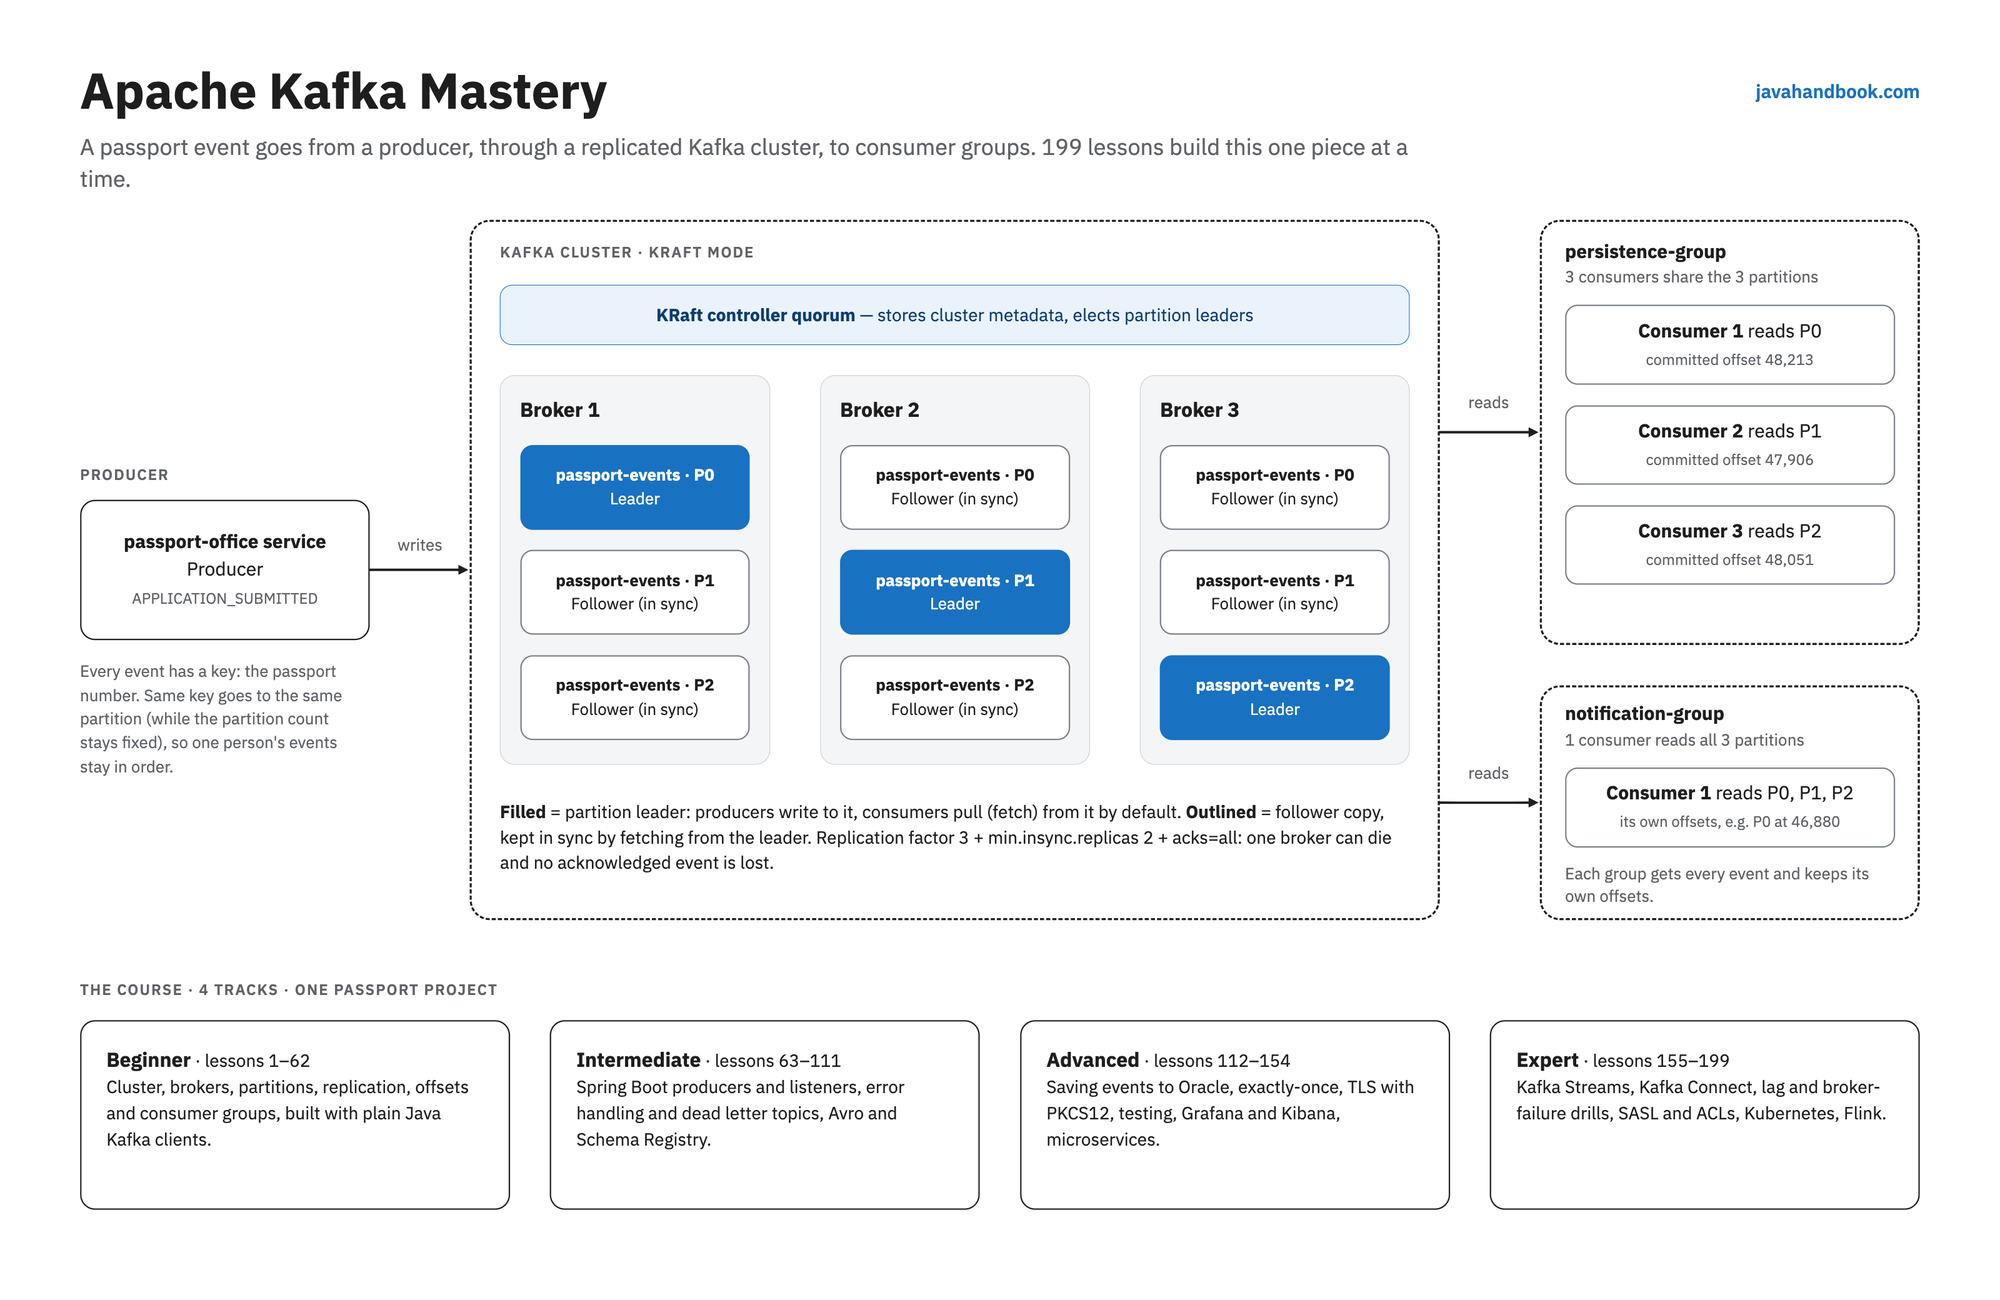
- A multi-topic Kafka cluster in KRaft mode — no ZooKeeper, no training wheels — with
passport-eventstracking every lifecycle transition (submitted, issued, renewed, revoked), a log-compactedpassport-statustopic holding the latest state per passport, and a high-volumepassport-scannedtopic capturing border-control scan events - Five independent microservices talking exclusively through Kafka — a passport office that accepts REST requests and fires events, a persistence service writing to Oracle, a notification service alerting applicants, a fraud watchlist service flagging suspicious applications, and an audit archive keeping an immutable record of everything
- A real-time streaming pipeline built with Kafka Streams — a fraud-detection topology that windows
passport-scannedevents and raises an alert when the same passport clears multiple border gates inside a suspicious time window - Full Avro schema management with Schema Registry — passport events versioned, evolved, and protected by compatibility rules so a v2 consumer can safely read a v1 event without blowing up
- A production-grade secured cluster — TLS encryption with PKCS12 keystores, SASL/SCRAM authentication, per-service ACLs, and payload-level AES-GCM encryption for passport numbers and biometric hashes
- The whole system observable, tested, and Kubernetes-ready — Grafana dashboards for consumer lag and throughput, Kibana for correlated log search, Testcontainers integration tests for the full produce→persist flow, and finally the five services redeployed onto Kubernetes with Strimzi managing the cluster
Key Takeaway Skills
By the end of this course you will be able to:
- Design a partition strategy for a given workload — key ordering, throughput targets, and consumer parallelism — instead of guessing at the number
- Write producers and consumers with the right delivery guarantee for the problem: at-most-once, at-least-once, or exactly-once, and know the cost of each
- Diagnose consumer lag and rebalancing issues — read a lag graph, identify the cause, and fix it without touching what isn’t broken
- Build a real-time streaming pipeline with Kafka Streams, including stateful operations and windowed aggregations
- Reason about trade-offs — throughput vs. durability, exactly-once vs. at-least-once, compaction vs. retention — the way you’d need to in a design review or incident postmortem
- Operate a Kafka cluster in production: monitor it, tune it, and understand what the broker is doing when things go wrong.
— the kind of decisions that show up in system design interviews and architecture reviews alike.
Who This Course Is For
I've designed this for:
- Backend and platform engineers who keep hearing “we should use Kafka” in design meetings and want to actually understand what that means
- Software architects evaluating event-driven patterns for microservices, fintech, or data platforms
- Engineers transitioning into distributed systems who want a solid foundation rather than scattered tutorials
- Anyone preparing for system design interviews, where Kafka appears constantly as a building block for scalable architectures
You don’t need prior Kafka experience. You need a willingness to build the mental model correctly from the start.
Prerequisites
To get the most out of this course, you should be comfortable with:
- Programming in Java (or another JVM language), most examples use Java 21 and Spring Boot
- Basic understanding of distributed systems concepts (a plus, not required) — what a network partition is, why consistency is hard.
- Familiarity with the command line and basic Docker usage, since we'll spin up local Kafka clusters for hands-on labs
No prior Kafka experience needed.
The Most Rewarding Outcome
Here's what I most want for you, beyond passing quizzes or finishing exercises:
I want the next time you're in an architecture discussion, and someone says "let's just add Kafka here," for you to be the person who can ask the right question back — "what problem are we actually solving, and does Kafka's trade-offs fit it?" — and then confidently help design the answer.
That shift — from recognizing a buzzword to wielding a tool with judgment — is the real outcome of this course. Code samples will fade from memory eventually; that architectural instinct won't.
Let's go build it...
You'll walk away able to look at a Kafka architecture diagram — or a production incident — and actually understand what's happening underneath, not just recognize the vocabulary. That's the gap that separates engineers who use Kafka from engineers who are trusted to design and fix Kafka systems.
This course closes it, and it's the difference that gets you handed the event-driven architecture project instead of watching someone else take it.